به نظر میرسد که بزها ابتدا حدود ده هزار سال پیش در کوههای زاگرس ایران اهلی شده باشند
Model outputMatches the reference
Speech recognition and text-to-speech models for Persian (Farsi), trained by Oncilla AI. Open weights, 8.8% word error rate on FLEURS, and it runs on a laptop.
Built on NVIDIA Nemotron and NeMo. Trained on 1,181 hours of openly licensed Persian speech.
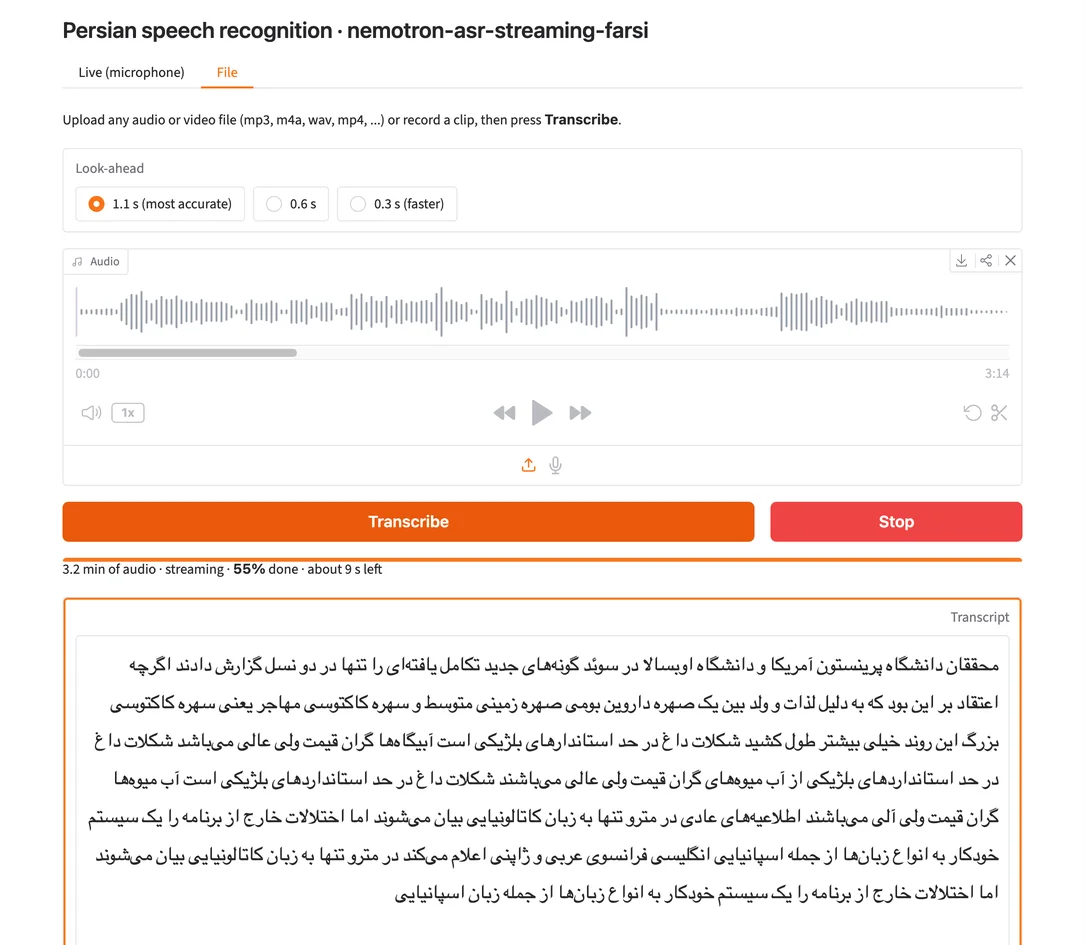
Four clips from the FLEURS test set, speech the model never trained on. Press play, then compare with the transcript below it.
به نظر میرسد که بزها ابتدا حدود ده هزار سال پیش در کوههای زاگرس ایران اهلی شده باشند
اینترنت عناصر ارتباط جمعی و بین فردی را با هم ترکیب میکند
کاری غذایی است که با گیاهان و ادویهها همراه با گوشت یا سبزیجات تهیه میشود
گیاهان با فتوسنتز غذای خود را از خورشید تهیه میکنند آنها همچنین سایه فراهم میکنند
These are four of the clips the model gets exactly right, picked to show what it does at its best. Across the whole
FLEURS test set it makes 8.8 word errors per 100 words (see the results below). “Matches the reference” is after
standard Persian text normalization, which ignores punctuation and the half-space (ZWNJ) versus space.
Audio:
FLEURS Persian test set, © Google, CC BY 4.0.
Streaming recognition with 0.3 to 1.1 seconds of delay. Words appear while the speaker is still talking.
Podcasts, interviews, films. Long recordings are processed in a stream, so length is not a problem.
About 10 times faster than real time on an Apple M1, on CPU or GPU, or on your own servers. No data leaves your machine.
A 109.5M-parameter Persian speech synthesis model with voice cloning from a few seconds of audio. It runs on a CPU.
سلام، حال شما چطور است؟ امیدوارم روز خوبی داشته باشید.
مادر کتاب را روی میز اتاق گذاشت و پنجره را باز کرد.
شرکت آنتروپیک مدلی اقتصادی منتشر کرده که نشان میدهد هوش مصنوعی چگونه میتواند اقتصاد آمریکا را تا سال ۲۰۳۰ تغییر دهد.
Each voice is cloned from a five-second prompt of a Mozilla Common Voice speaker (CC0) that the model never saw in training. Press play on the prompt, then on the generated speech. The open weights are released under CC BY-NC 4.0 (non-commercial use).
Word error rate on the FLEURS Persian test set, where lower is better. Within about a point of the best commercial systems, with weights you can run yourself.
| Model | Access | FLEURS Persian | Conversational speech |
|---|---|---|---|
| ElevenLabs Scribe v1Commercial API | Closed | 7.8% | not reported |
| Gemini Flash 2Commercial API | Closed | 8.0% | not reported |
| Oncilla AI · nemotron-asr-streaming-farsiStreaming, 600M parameters | Open weights | 8.8% | 26.0% |
| Shenava Koochik v1.0Streaming, 114M parameters | Open weights | 10.6% | not reported |
| Whisper large-v3 | Open weights | 24.0% | not reported |
| NVIDIA stt_fa FastConformerPrevious best NVIDIA Persian model | Open weights | 24.2% | 54.4% |
Our model and NVIDIA's were scored by us on the same 852 FLEURS Persian test clips with the same Persian text normalization. The other numbers are the ones their publishers report (ElevenLabs, Gemini Flash 2 and Whisper large-v3: elevenlabs.io/speech-to-text/persian; Shenava: its Hugging Face model card), and each used its own text normalization, so small differences are not meaningful. “Conversational speech” is a held-out test set of 9,154 YouTube and film clips (about 8 hours) that none of the models trained on.
Turn Persian video and audio into timed text for broadcasters, creators and educators.
Make interviews, podcasts and archives searchable, from newsroom back catalogs to oral histories.
Generate narration in Persian without booking a studio, including cloned voices.
Live captions for deaf and hard-of-hearing people, and spoken versions of text for blind readers.
Transcribe customer calls and meetings in Persian for quality review and analytics.
Pronunciation practice and listening exercises with accurate transcripts.
The model, the full training recipe, evaluation scripts and a local web app for live microphone transcription.
Weights: OpenMDW-1.1 · Code: Apache-2.0A compact Persian text-to-speech model with voice cloning, and the code that trained it.
Weights: CC BY-NC 4.0 · Code: MITThe open models are free to use under their licenses. If you need them adapted to your audio, vocabulary or accents, or running privately on your own infrastructure, write to us.
mehdi@oncillaai.com →
Co-founder, Oncilla AI · AI researcher & system architect
Mehdi trained and released these models at Oncilla AI. He has spent 15+ years building machine-learning systems in production, holds a PhD in Computer Science, and was a tenure-track Assistant Professor researching NLP.